
You're paying three times to ask the same question
You ask GPT-5.6 to rewrite a landing page headline. It gives you something serviceable. You wonder if Claude would do better, so you open a tab, paste the same prompt, and get something you like more. Then you want a third read, so Gemini gets a tab too.
Three tabs. Same prompt typed three times. Three answers you now have to hold in your head and compare by eye. And when you come back to it on Thursday, you have no idea which tab had the good version. That's the workflow most people have settled into. It costs about $60 a month and it's held together by browser tabs.
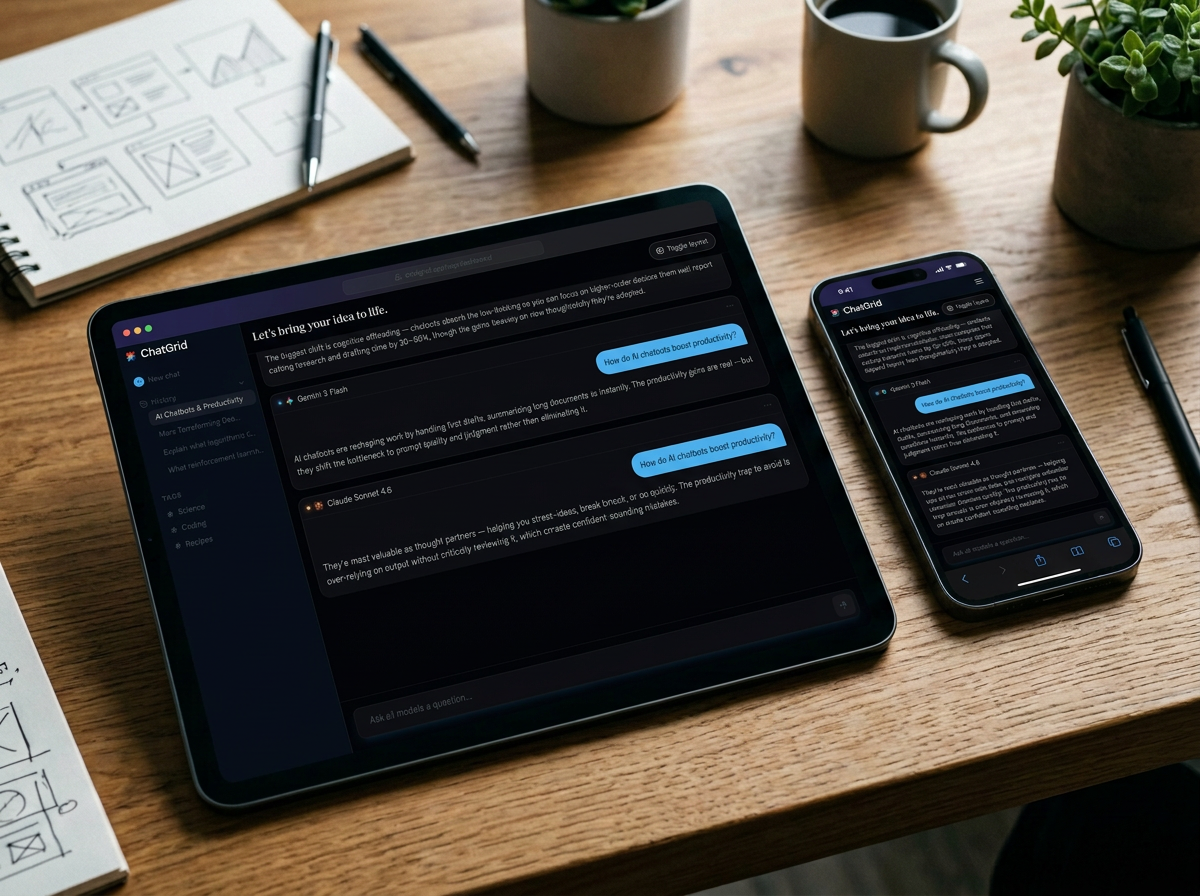
ChatGrid runs the prompt once, against every model at the same time, on one screen.
What you actually get
13 flagship models from 5 providers, in one workspace:
- OpenAI: GPT-5.6 Luna, GPT-5.6 Terra, GPT-5.6 Sol, GPT-5.5
- Anthropic: Claude Opus 5.0, Claude Sonnet 5, Claude Haiku 4.5
- Google: Gemini 3.6 Flash, Gemini 3.5 Flash, Gemini 3.5 Flash Lite
- xAI: Grok 4.6
- DeepSeek: DeepSeek v4 Pro, DeepSeek v4 Flash
No API keys. No integrations to configure. No separate logins. You type a prompt into one box and watch 3 to 8 models answer in parallel cards, depending on your plan.
The math nobody runs
Here's what a serious multi-model habit costs if you build it out of subscriptions:
ChatGrid Pro is $16.67/month, billed annually at $200. That covers all three providers plus xAI and DeepSeek, and it runs five models on one prompt at once.
You are paying about three and a half times as much for a worse workflow. To be straight about the trade: the direct subscriptions give you things ChatGrid doesn't, like ChatGPT's image generation, voice mode, and custom GPTs. If those are core to your day, keep the one you actually use and let ChatGrid cover the rest. Most people don't need three flagship chat subscriptions. They need one prompt to hit three flagship models.
Comparing answers is the boring part, so ChatGrid does it
Running the same prompt against five models is easy. Reading five answers, spotting where they disagree, and working out which one to trust is the part that eats your afternoon.
ChatGrid reads every response and writes a synthesized summary. Where the models agree, where they diverge, and what the combined answer looks like. On Elite you can summarize across multiple chats, not just one.
This is the difference between a multi-model tool and a multi-model tab manager. Parallel output is a feature anyone can build. Something that tells you what the parallel output means is the reason to open ChatGrid instead of four tabs.
Where model disagreement actually matters
Running everything through five models is overkill. Some questions genuinely benefit:
Anything with a house style. Ask five models for the same product description and you get five voices. One of them is closer to yours than the others, and you'll know which in about four seconds of reading, versus twenty minutes of iterating on a single model that keeps missing.
Technical decisions with more than one right answer. Schema design, architecture calls, library choices. When four models independently land on the same approach, that's signal. When they split, that's a flag that your question was underspecified, and finding that out in one pass is worth the subscription on its own.
Factual claims you're about to publish. Models hallucinate differently. Consensus across five isn't proof, but a claim that only one model makes is worth checking before it goes in the deck.
Explanations of things you don't understand yet. Different models reach for different analogies. One of them will click.
Where it's not worth it: routine drafting, code you'll test anyway, and anything where you already know what good looks like. Use one card and move on.
Your prompts stop disappearing
Every chat is saved, searchable, and tagged however you want. By project, by client, by topic. Filter down to the four conversations from that campaign in October instead of scrolling three separate chat histories trying to remember which platform you used.
The prompt you spent forty minutes refining last month is worth keeping. Right now it's probably gone.
Pricing
Pro is the one most people want. Five models is enough to see real disagreement, and single-chat summaries are where the time savings show up.
Try it against something you already answered
The honest test isn't reading about this. Take a prompt you ran last week in ChatGPT, run it through ChatGrid, and see whether a different model gave you a better answer than the one you shipped.
Sometimes it won't. That's useful too. You'll stop wondering.